[ENHANCEMENT]: Robin Hood Hashing performance improvement - would a PR be welcome?
维护者通常 1 天内回复
还没有人认领这个 Issue。
评估
- 难度
- 5/5
- 预计耗时
- 一周以上
- 新手友好度
- 35/100
- Issue 类型
- 功能
- 描述清晰度
- 需要澄清
- 活跃度
- 冷清
- 技术栈
- cpp
- 领域
- hpc, performance
调研方向
首先查看引用的 GPURobinHoodHashing 对比内容和博客文章,然后检查 cuco::static_map 当前如何提供 cuco::linear_probing 和 cuco::double_hashing。该 issue 需要 maintainer 指导 Robin Hood hashing 是否适合作为另一种策略,以及 PR 应遵循什么结构;确定一致同意的实现范围后即可完成。
由索引模型根据 Issue 内容生成。
描述
Is your feature request related to a problem? Please describe.
See below.
Describe the solution you'd like
I recently decided, mostly for fun, to challenge myself to re-implement a concurrent hashing table based on Robin Hood hashing that I designed and built in 2016 as part of a project on GPU-accelerated Latent Dirichlet Allocation, but never actually got to work.
This time, I did get it to work - and according to my benchmarks, the resulting table has higher get throughput than cuCollections' static_map with either linear probing or double hashing, by quite a bit at sufficiently high load factors.
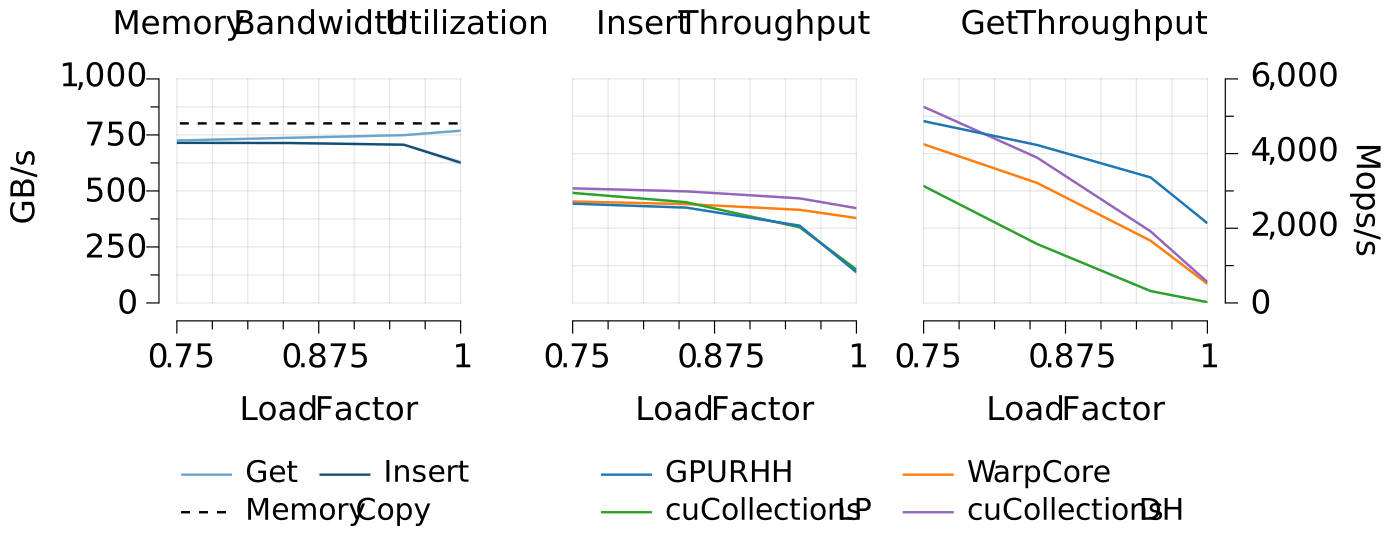
Repo for this comparison: https://github.com/aterenin/GPURobinHoodHashing. I've also got a blog post around some of the ideas and why I found this exercise interesting: https://avt.im/blog/sculpting-fragile-glass/.
I don't know what Nvidia's policy on external contributions to this library is, but if there is interest, I'd love to contribute the core algorithmic ideas to cuCollections so that other people can use them. I'd image this would look like a third option like cuco::double_hashing or cuco::linear_probing but which would implement the Robin Hood strategy. It'd probably improve performance in static_map and possibly other data structures depending on how advanced your templating logic is.
Would a PR on this be welcome? If yes, I'll put one together - I'd appreciate pointers on the cleanest way to add this structure-wise in case you have any: I value high-quality code and will work to do everything the right way. If not, no worries, feel free to just close the issue. Please let me know either way.
Describe alternatives you've considered
No response
Additional context
No response
- 主要语言
- Cuda
- 星标
- 674
- 派生
- 123
- 平均合并
- 3 天 9 小时
- 30 天内合并 PR
- 10
环境准备
在浏览器里用你自己的 GitHub 账号启动这个项目的开发容器。
- 没有 Dockerfile 或 Docker Compose 文件
- 有 Pull Request 模板
- 阅读贡献指南
从这里开始
- 先读完整个 Issue,再读项目的贡献指南。
- 在 Issue 下留言说明你要接手 —— 这能避免两个人做同样的事。
- Fork 仓库,在一个分支上完成修改。
- 提交 Pull Request,并在描述里引用这个 Issue 编号。
NVIDIA/cuCollections 的其他 Issue
-
Add cuco::detail::stream_sync(cuda::stream_ref) to centralize CCCL version-specific API naming可能重新可做 @0z5a 于 31 天前认领,目前没有进行中的 PR。 未关闭
难度 2/5 1-3 小时 新手友好度 74/100
NVIDIA/cuCollections#840 · 1 条评论 ·
维护者通常 1 天内回复
-
nvidia-runners
难度 1/5 1-3 小时 新手友好度 25/100
NVIDIA/cuCollections#853 ·
维护者通常 1 天内回复
-
good first issue P2: Nice to have type: improvement
难度 4/5 3-5 天 新手友好度 38/100
NVIDIA/cuCollections#805 · 4 条评论 ·
维护者通常 1 天内回复
-
[FEA] Add MPSC/MPMC concurrent queue可能重新可做 @sleeepyjack 于 271 天前认领,目前没有进行中的 PR。 未关闭maintainer-only type: feature request
NVIDIA/cuCollections#791 · 已指派 1 人 ·
维护者通常 1 天内回复
-
[ENHANCEMENT]: Make cuco code NVRTC-compatible可能重新可做 @0z5a 于 31 天前认领,目前没有进行中的 PR。 未关闭helps: rapids type: feature request
NVIDIA/cuCollections#695 · 6 条评论 · 2 个 reaction · 已指派 1 人 ·
维护者通常 1 天内回复
查看 NVIDIA/cuCollections 的全部 Issue
相似的 Issue
-
难度 2/5 1-3 小时 新手友好度 72/100
-
难度 2/5 1-3 小时 新手友好度 72/100
ROCm/rocm-systems#13525 ·
维护者通常 2 天内回复
-
难度 2/5 1 小时以内 新手友好度 80/100
-
[Bug]: copy-assigning a boundary condition does not compile: `Bc::operator=` assigns to the `const` reference `m_domain`可能已有人在做 @gouarin 于 10 天前认领。 未关闭bug good first issue
难度 2/5 1-3 小时 新手友好度 78/100
维护者通常 1 天内回复
-
amr bug 🔥 diagnostics outputs
难度 2/5 1-3 小时 新手友好度 78/100
维护者通常 1 天内回复