All datapoints does not always reach the database in multiprocessing scenario for the `flush_interval < 1000`
@bednar 已经在做这个了。
开始于 2022年10月13日。
评估
这个 Issue 还没有评估数据。
描述
Steps to reproduce:
Run the following code:
import time
import multiprocessing
from influxdb_client import InfluxDBClient, Point, WritePrecision
from influxdb_client.client.write_api import WriteType, WriteOptions
from influxdb_client.client.util.multiprocessing_helper import MultiprocessingWriter

token = "TOKEN HERE=="
org = "my-org"
bucket = "reproduce_bug"

def write_process(q):
    # with InfluxDBClient(url="http://localhost:8086", token=token, org=org) as client:
    with MultiprocessingWriter(url="http://localhost:8086", token=token, org=org, write_options=WriteOptions(batch_size=1000)) as writer:
        # write_api = client.write_api(write_options=WriteOptions(batch_size=1000))#, write_type=WriteType.batching))
        now = time.time_ns()
        processed = 0
        while True:
            i = q.get()
            point = Point.from_dict({
                "measurement": "bug_test",
                "tags": {},
                "fields": {
                    "id": i,
                    "temp": 2.2324234232,
                    "temp2": 221,
                    "temp3": 2
                },
                "time": now+processed
            }, WritePrecision.NS)

            writer.write(bucket=bucket, record=point)
            processed += 1
            print(processed)

def feeder_process(q):
    for i in range(250000):
        q.put(i)

def feeder_process2(q):
    for i in range(250000):
        q.put(i)

if __name__=='__main__':
    q = multiprocessing.Queue()
    write_p = multiprocessing.Process(target=write_process, args=(q,))
    feeder_p = multiprocessing.Process(target=feeder_process, args=(q,))
    feeder_p2 = multiprocessing.Process(target=feeder_process2, args=(q,))
    write_p.start()
    feeder_p.start()
    feeder_p2.start()
    write_p.join()
    feeder_p.join()
    feeder_p2.join()
Expected behavior:
The code above produces 500 000 arbitrary data points with unique IDs. When the code has processed all the 500 000 data points, it is expected that all of them should be present in the InfluxDB database, which can be verified by running a |> count() on the measurement.
Actual behavior:
By running a |>count() on the data in e.g., Chronograf, there are sometimes less than 500 000 samples. This does not happen every time and it cannot seem to reproduce with MultiprocessingWriter instead of with the normal write_api in the code snippet. In my real-world scenario, however, the bug persists even with MultiprocessingWriter. I have tried to increase the frequency of the bug by adding more feeder processes, which seems to have some effect on it.
The actual scenario where the bug started to appear is similar to this code snippet. I have several processes that produce data and place it into a results queue, the results queue is read by a handler process that writes the results to the database. In the real scenario, there is always between around 5-30 samples missing. I have removed the real data in the real scenario and replaced it with a simple ID field to track the packets and to ensure that the data isn't the cause. I have also added unique timestamps to ensure that no data point is overwritten.
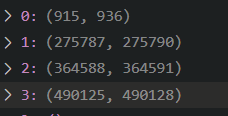
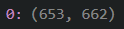
When analyzing the real-world scenario data I found several "gaps" in the IDs, which implies that the packet with IDs within the gaps are missing. I have attached a screenshot of my analysis of two tests below. In the top picture, 4 intervals with missing packets were identified, and in the second picture, only one was identified. Please let me know if the images need further explanation.
Specifications:
- Client Version: 1.26.0
- InfluxDB Version: 2.1.1
- Platform: Windows 10, influxdb in docker
- 主要语言
- Python
- 星标
- 792
- 派生
- 186
- PR 合并指标
- 30 天内没有已合并 PR
环境准备
- 没有 Dockerfile 或 Docker Compose 文件
- 有 Pull Request 模板
- 没有贡献指南
从这里开始
- 先读完整个 Issue,再读项目的贡献指南。
- 在 Issue 下留言说明你要接手 —— 这能避免两个人做同样的事。
- Fork 仓库,在一个分支上完成修改。
- 提交 Pull Request,并在描述里引用这个 Issue 编号。
influxdata/influxdb-client-python 的其他 Issue
-
bug
难度 2/5 1-3 小时 新手友好度 68/100
influxdata/influxdb-client-python#613 · 7 条评论 ·
-
bug
难度 3/5 1-2 天 新手友好度 65/100
-
难度 3/5 1-2 天 新手友好度 45/100
influxdata/influxdb-client-python#694 · 6 个 reaction ·
-
bug
难度 3/5 1-2 天 新手友好度 30/100
influxdata/influxdb-client-python#693 · 2 条评论 · 1 个 reaction ·
-
难度 4/5 3-5 天 新手友好度 35/100
查看 influxdata/influxdb-client-python 的全部 Issue
相似的 Issue
-
难度 2/5 1-3 小时 新手友好度 85/100
mozilla/bedrock#17413 · 1 个 reaction ·
维护者通常 2 天内回复
-
instance instance add
难度 2/5 1-3 小时 新手友好度 68/100
searxng/searx-instances#943 · 1 条评论 ·
-
难度 2/5 1-3 小时 新手友好度 68/100
维护者通常 1 天内回复
-
bug tools
难度 2/5 1-3 小时 新手友好度 88/100
维护者通常 1 天内回复
-
bug
难度 2/5 1-3 小时 新手友好度 86/100
lance-format/lance#9655 ·
维护者通常 2 天内回复