[BUG] Unescaped caption text breaks WebVTT and SMPTE-TT output
メンテナーはふだん 1 日以内に返信
まだ誰も着手していません。
評価
調査の方向性
Start by tracing how caption text is written by the WebVTT and SMPTE-TT output paths; the issue does not name source files or tests. Reproduce with the linked 77-byte RCWT sample and the listed commands, including parsing the XML output. Done when the caption remains visible as literal text in WebVTT and SMPTE-TT output parses as valid XML, while generated formatting remains intact.
索引モデルが issue の本文から書いたものです。
説明
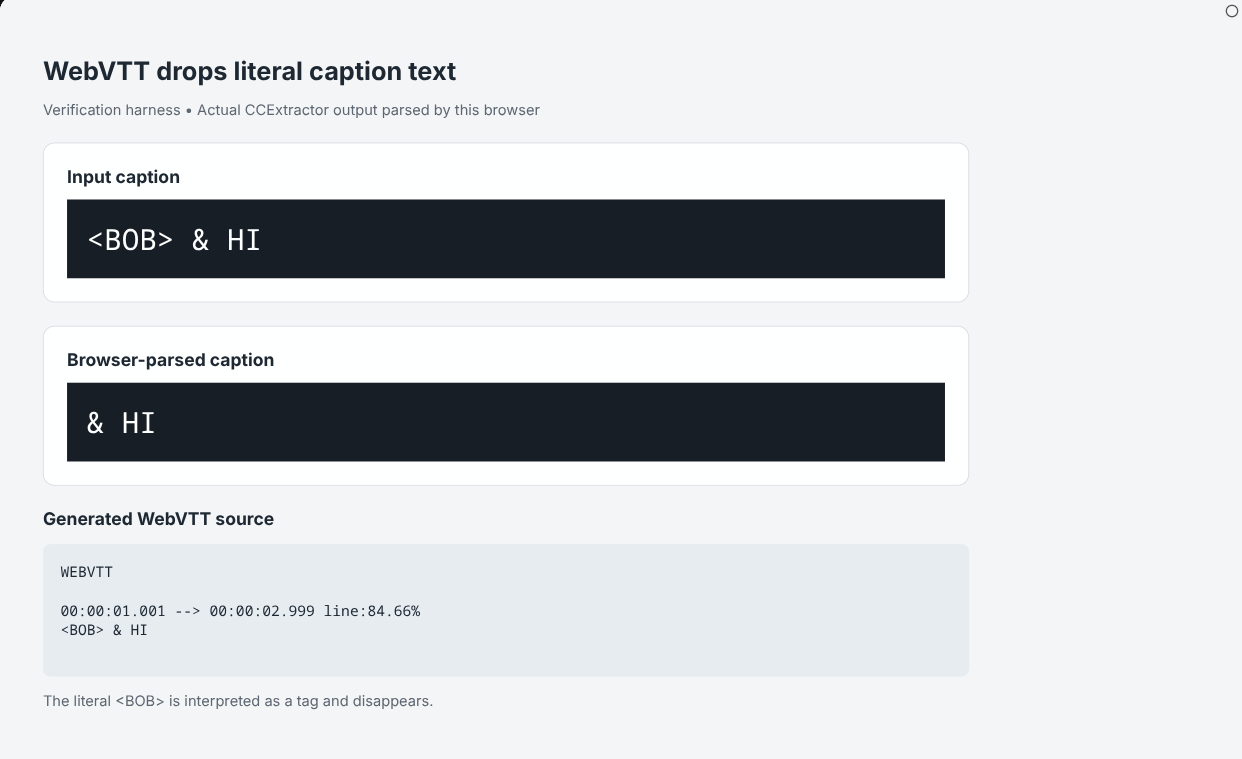
Caption text <BOB> & HI is written without escaping: WebVTT loses <BOB> when rendered, and SMPTE-TT produces invalid XML. Both commands exit with status 0.
Tested: Linux x86_64, CCExtractor 0.96.5 at 6c9fc900. Regression status unknown.
Reproduce
Download markup.bin, a 77-byte RCWT sample containing that caption, then run:
ccextractor markup.bin --out=webvtt -o markup.vtt
ccextractor markup.bin --out=smptett -o markup.xml
python3 -c 'import xml.etree.ElementTree as E; E.parse("markup.xml")'
Actual result
- WebVTT: Chromium's
cue.getCueAsHTML().textContentgives& HI; the literal<BOB>is treated as a tag. - SMPTE-TT: output contains
<span><BOB> & HI. XML parsing fails:not well-formed (invalid token): line 20, column 21. - Control: transcript output preserves the full caption. A
HELLO WORLDsample produces parseable XML.
Sample generator and control · Generated WebVTT · Generated XML
Expected
Preserve <BOB> & HI as visible text and produce valid XML. Escape literal caption characters, e.g. <BOB> & HI, without escaping encoder-generated formatting.
Related: #1703 proposed escaping for SRT but was closed without merging.
Screenshot
Actual generated WebVTT parsed in a browser verification page:
- 主要言語
- C
- スター
- 912
- フォーク
- 598
- 平均マージ
- 2日 7時間
- マージ済み PR(30日)
- 29
環境構築
- Dockerfile・Docker Compose ファイルなし
- プルリクエストのテンプレートあり
- コントリビューションガイドを読む
はじめの一歩
- issue を最後まで読み、次にプロジェクトのコントリビューションガイドを読みます。
- 着手することを issue にコメントします — 二人が同じ作業をするのを防げます。
- リポジトリをフォークし、ブランチを切って変更します。
- issue 番号を参照したプルリクエストを送ります。
CCExtractor/ccextractor のほかの issue
-
Heap OOB read in parse_ad_cdp: cc_count not bounded by packet length対応中かも @Nikhil-jaiswal007 が 6 日前に担当しました。 オープン
難易度 2/5 1〜3時間 初心者へのやさしさ 78/100
CCExtractor/ccextractor#2425 · コメント 1 件 ·
メンテナーはふだん 1 日以内に返信
-
[BUG] Heap buffer overflow in parse_PMT with C0/C1 section length対応中かも @kun-codes が 8 日前に担当しました。 オープン
難易度 2/5 1〜3時間 初心者へのやさしさ 78/100
CCExtractor/ccextractor#2419 ·
メンテナーはふだん 1 日以内に返信
-
[BUG] Filename sequence expansion (`+`) panics on numeric values exceeding `i32::MAX`対応中かも @muntasir-396 が 12 日前に担当しました。 オープン
難易度 2/5 1〜3時間 初心者へのやさしさ 82/100
CCExtractor/ccextractor#2402 ·
メンテナーはふだん 1 日以内に返信
-
[BUG] ISDB decoder ignores the payload length: heap-buffer-overflow in parse_statement, plus a one-byte overflow in get_text対応中かも @pranayr710 が 3 日前に担当しました。 オープン
難易度 4/5 3〜5日 初心者へのやさしさ 55/100
CCExtractor/ccextractor#2434 ·
メンテナーはふだん 1 日以内に返信
-
[BUG] WTV read_header(): unchecked len and text_len from the file crash the parser (SEGV, 4 KB reproducer)対応中かも @pranayr710 が 3 日前に担当しました。 オープン
難易度 2/5 1〜3時間 初心者へのやさしさ 35/100
CCExtractor/ccextractor#2433 ·
メンテナーはふだん 1 日以内に返信
CCExtractor/ccextractor の issue をすべて見る
似ている issue
-
難易度 2/5 1〜3時間 初心者へのやさしさ 82/100
メンテナーはふだん 1 日以内に返信
-
elf_loader: Xtensa ignores the addend of R_XTENSA_GLOB_DAT / R_XTENSA_JMP_SLOT (C++ vtables)対応中かも @diplfranzhoepfinger が今日担当しました。 オープンelf_loader
難易度 2/5 1〜3時間 初心者へのやさしさ 72/100
espressif/esp-iot-solution#813 ·
メンテナーはふだん 1 日以内に返信
-
Status: Opened Type: Bug
難易度 1/5 1時間未満 初心者へのやさしさ 85/100
メンテナーはふだん 1 日以内に返信
-
難易度 1/5 1時間未満 初心者へのやさしさ 85/100
msys2/MSYS2-packages#6919 ·
メンテナーはふだん 1 日以内に返信
-
severity: low
難易度 2/5 1〜3時間 初心者へのやさしさ 76/100
luainkernel/lunatik#2221 ·
メンテナーはふだん 1 日以内に返信